
See what your AI agents are doing before your customers do.
Tracing, evaluation and alerting for production agents, so silent failures become visible failures.
- 48–72 HOURS
- TOP 3% ENGINEERS
- 100% REPLACEMENT
What we do.
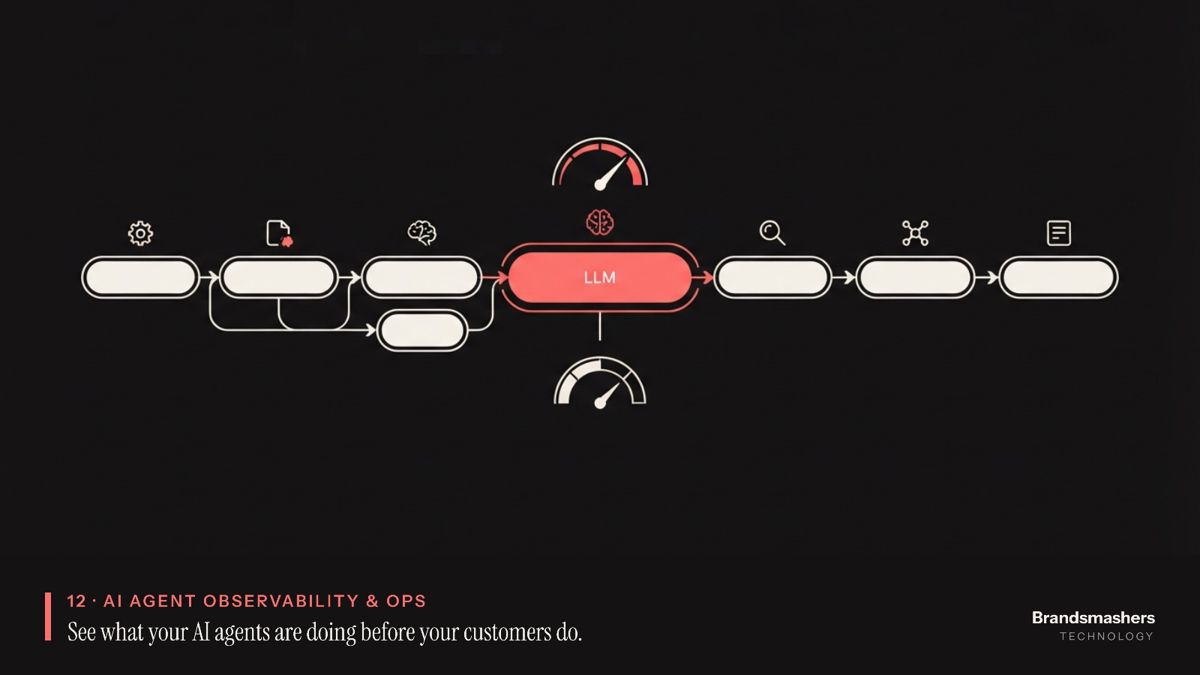
Trace every agent step
prompts, tool calls, outputs, cost and latency, tied to a single run so an engineer can replay it.
Evaluation suites that score quality on real cases, run before every release and on samples of live traffic.
Alerts on drift, loops, rising cost and bad decisions, routed to the people who can act.
Debugging dashboards for engineers and ops, built around the questions they ask during an incident.
Safe failure design
fallbacks, rate limits, human hand-off.
How we work.
We start by reading how your agents work today: the prompts, the tools they can call, the data they see and the decisions they make. We list how each one can go wrong, such as a wrong answer, a wrong action, a loop, a cost spike or a leak of data.
Then we add tracing, so every run leaves a record. Next we build an evaluation set from real cases, with expected outcomes agreed with the people who know the domain. We score quality automatically where we can and by human review where we must.
Only then do we add alerts and dashboards, because alerts without a quality baseline are noise. We finish with safe failure design: limits, fallbacks and clear hand-off to a person. We work in your repositories, on your tools where possible, and we avoid locking you into a single vendor.
Who this is for.
A CTO or head of engineering who has shipped an agent and cannot say how often it is wrong.
A team running several agents where nobody can tell which step caused a bad result.
A product owner who wants to change a prompt or model and needs proof that quality did not drop.
An operations lead who hears about agent mistakes from customers or support staff, not from monitoring.
A company preparing to expand agent use and wanting controls before volume grows.
What you get.
End-to-end tracing for your agents, with search and replay of any run.
An evaluation set built from your real cases, with scoring rules and a runner for releases.
Quality, cost, latency and hand-off views for engineers and operations.
Alerts with thresholds agreed with you, and a plan for who responds.
Safe failure design: fallbacks, rate limits and human hand-off paths.
A written operating guide covering change control for prompts and models.
- Top 3% of applicants
- Start in 48–72 hours
- Dedicated account manager
- 100% replacement guarantee
Typical timeline.
- 01
Weeks 1 to 2
Review of agents, failure modes and existing logs. Decide what to trace and how.
- 02
Weeks 3 to 5
Tracing in staging and then production. First dashboards for engineers.
- 03
Weeks 6 to 8
Evaluation set and scoring. Baseline measurements. Release checks added to your pipeline.
- 04
Weeks 9 to 10
Alerts, safe failure design and runbooks. Tune thresholds on real traffic.
- 05
Week 11 onward
Handover, with optional support while your team takes over.
Proof
150+ developers deployed, and about 3% of applicants pass our 4-gate vetting. 100% replacement guarantee.
Related work and reading.
 Case studyBuilding a debugging dashboard for a client's multi-agent AI systemRead the story
 Case studyCatching silent AI agent failures before they reached customersRead the story
 ArticleWhy AI agents need observability tooRead the article
 ArticleThe new engineering discipline nobody's hiring for yet: AI OpsRead the article
LET'S TALK. Start now.
Tell us what you're building. We'll come back with a plan and matched, pre-vetted engineers.
CONTACT