
AI that understands your industry's documents.
Custom extraction, classification and search for contracts, reports, claims and records.
- 48–72 HOURS
- TOP 3% ENGINEERS
- 100% REPLACEMENT
What we do.
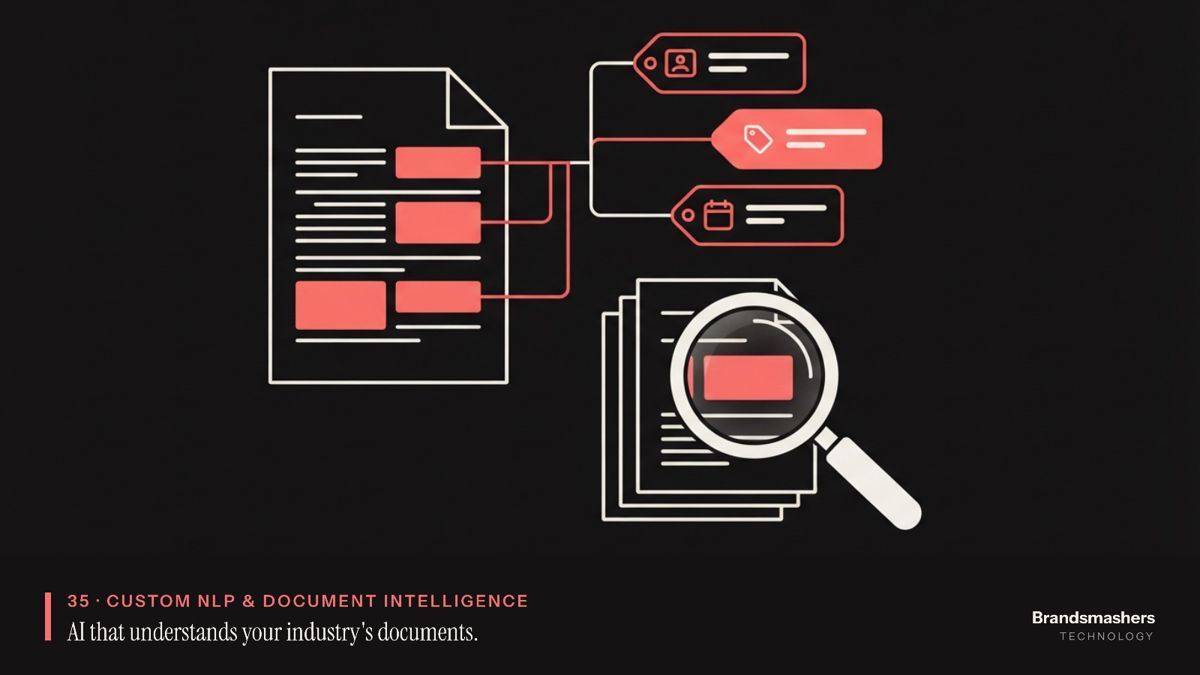
Clause and entity extraction tuned to your documents
parties, dates, amounts, obligations, renewal terms, claim fields and anything else your team keys in by hand.
Document classification and routing
identify what each file is and send it to the right queue, person or system.
Semantic search and question answering with citations
ask a question across thousands of files and get an answer that points to the exact passage.
Evaluation on your own labelled samples
accuracy measured on your documents, reported by field and document type, not on a public benchmark.
Private deployment options for sensitive data
run inside your cloud account or on your own infrastructure when documents cannot leave.
How we work.
We start by collecting a representative sample of your documents and agreeing, with your reviewers, what a correct answer looks like. We label a test set first, before building anything, so we can score every approach honestly, including a general tool as the baseline. Then we build the simplest thing that clears your bar, add human review for low-confidence cases, and connect results to your systems. After launch we track accuracy on real traffic and retrain when the documents change.
Who this is for.
Legal and contract teams who review the same clause types again and again.
Insurance, claims and operations teams sorting and keying in large volumes of mixed documents.
Compliance and risk teams who need to find specific terms across a large archive.
Companies whose data cannot go to a public AI service, for contractual or regulatory reasons.
Teams that tried a general tool, got good-looking but unreliable output, and need numbers they can defend.
What you get.
A labelled evaluation set built with your reviewers, and a written definition of each field and category.
A baseline score from a general tool, so you can see what customisation adds.
A working extraction, classification or search system, deployed where you need it.
A review interface or queue for low-confidence cases, with corrections stored for retraining.
Integrations to your document store, case system or workflow tool.
An accuracy report by field and document type, and a monitoring set-up.
Documentation and training for your team.
- Top 3% of applicants
- Start in 48–72 hours
- Dedicated account manager
- 100% replacement guarantee
Typical timeline.
Narrow projects, such as one document type, can move faster.
- 01
Weeks 1 to 2
document sampling, field and category definitions, labelling of the test set, baseline testing.
- 02
Weeks 3 to 6
model and pipeline build, tuning against the test set, review workflow.
- 03
Weeks 6 to 8
integration, pilot on live documents with human review.
- 04
Weeks 8 to 10
rollout, monitoring, handover.
Proof
150+ developers deployed, and about 3% of applicants pass our 4-gate vetting. Your engineer can be in your standup in 72 hours, and our replacement guarantee is 100%.
You might be able to. We recommend testing that first. If a general tool clears your accuracy bar on your documents, use it. We build custom only when the test shows a gap or when data cannot leave your environment.
Related work and reading.
 Case studyAutomated contract clause extraction using custom NLPRead the story
 Case studyBuilding a document classification system for a legal back officeRead the story
 ArticleCustom NLP vs. off-the-shelf AI tools: when you need customRead the article
 ArticleWhat document intelligence can do for teams drowning in paperworkRead the article
LET'S TALK. Start now.
Tell us what you're building. We'll come back with a plan and matched, pre-vetted engineers.
CONTACT