
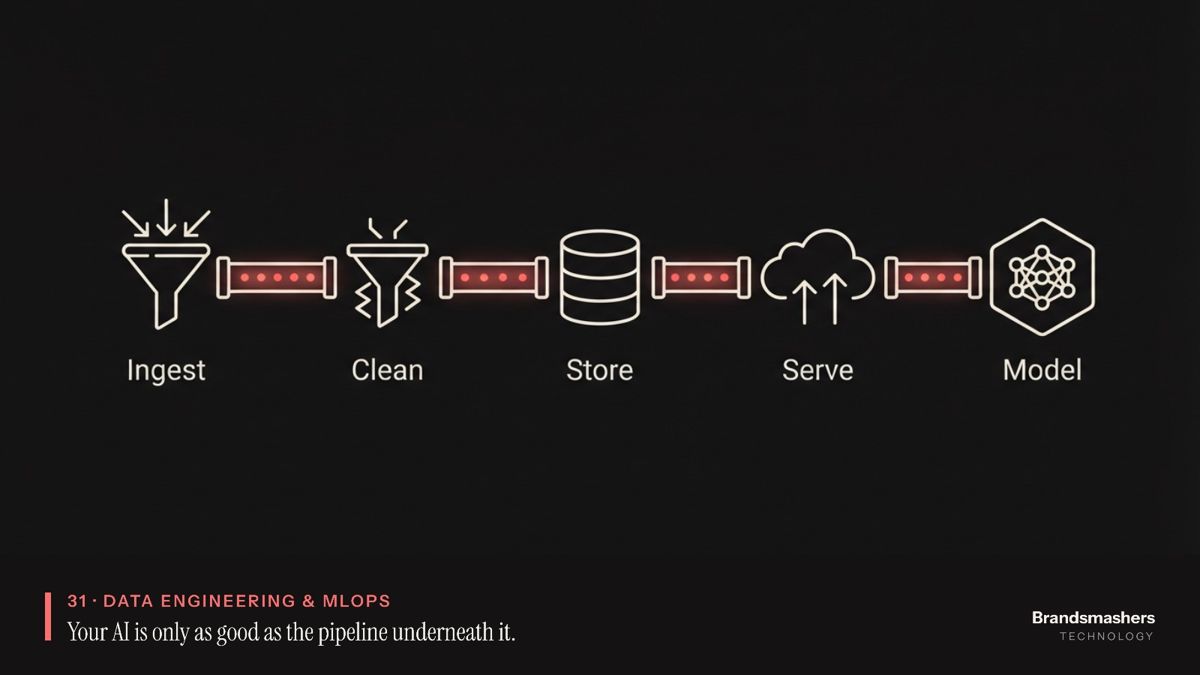
Your AI is only as good as the pipeline underneath it.
Senior data engineers, data architects and MLOps leads who build the data foundation and the deployment pipeline your AI depends on. In your standup within 72 hours.
- 48–72 HOURS
- TOP 3% ENGINEERS
- 100% REPLACEMENT
Gartner predicts that through 2026, organisations will abandon 60% of AI projects that are not supported by AI-ready data. In the same research, 63% of organisations either do not have, or are unsure if they have, the right data management practices for AI (Gartner, Feb 2025). The model is rarely what fails. The data feeding it arrives late, means different things in different systems, or breaks without anyone noticing. The same goes for the path that takes a model from a notebook to production. Fixing both is plain engineering work, and it pays off before any new model is trained.
- 48–72hfrom first call to engineers in your standup
- Top 3%of applicants, vetted for the work
- 100%replacement guarantee on every hire
What we build.
**Who joins your team:** Data/MDM/ETL architects, Snowflake and Databricks leads, MLOps engineers and AI/ML architects. All senior, all through our 4-gate vetting (about 3% pass).
Modern data platforms on Snowflake, Databricks, AWS and Azure.
Storage, compute, access control and cost controls designed together, with clear layers from raw to curated data.
Batch and real-time pipelines (ETL/ELT, streaming) with tests and monitoring.
Schema checks, freshness checks, volume alerts and retries, so a broken feed is caught in minutes.
Master data management and data quality, including Reltio and MDM architecture.
One agreed definition of customer, product and supplier, with matching, survivorship rules and stewardship workflows.
MLOps
feature stores, model registries, CI/CD for models, drift monitoring.
Data governance
lineage, access control and documentation people actually use.
Who this is for.
A CTO whose data science team has working models that nobody can deploy safely.
A head of data with five definitions of "active customer" and a board that wants one number.
A product team that needs near-real-time data and has only nightly batch jobs.
A company moving to Snowflake or Databricks that wants it done once, with cost and access controls in place.
A leader who has been told "the data isn't ready" for AI and needs a plan with order and scope.
How we work.
Assess before building.
We trace a few important datasets end to end and test the three questions: where it came from, how fast you know it broke, and whether a new engineer can find it.
Pick one thin slice.
One use case, built through ingestion, quality checks, serving and monitoring.
Test like software.
Pipelines and models go through version control, review and automated checks.
Name owners.
Each important dataset and model has a person who answers when it breaks.
Hand over.
Runbooks, diagrams and paired working, so your team runs it without us.
What you get.
A target architecture and a prioritised roadmap, in plain language.
Production pipelines with tests, alerts and documented ownership.
Data quality rules and, where needed, a master data design.
A model registry, automated promotion path and rollback procedure.
Drift and performance monitoring for models in production.
Lineage and access documentation that stays current.
- Top 3% of applicants
- Start in 48–72 hours
- Dedicated account manager
- 100% replacement guarantee
Typical timeline.
- 01
Weeks 1 to 2
assessment, architecture and agreed first slice.
- 02
Weeks 3 to 6
build the first pipeline or model path, with tests and monitoring.
- 03
Weeks 7 to 8
hardening, rollback drills, documentation and handover.
- 04
After that
extend to more datasets or models, or step back to a lighter retainer.
Proof
For a global hardware manufacturer we turned manual knowledge-base processing into real-time, structured, API-ready data, with 1,000s of products ingested and processed at scale.
Not always. Many problems come from missing tests, ownership and definitions, and those can be fixed on the platform you have. We say so when a migration is not justified.
Related work and reading.
 Case studyBuilding an MLOps pipeline that cut model deployment time by 70%Read the story
 Case studyRebuilding a client's data pipeline to support real-time AI featuresRead the story
 ArticleWhy every AI initiative depends on boring data engineeringRead the article
 ArticleMLOps explained: the infrastructure behind every good AI productRead the article
LET'S TALK. Start now.
Tell us what you're building. We'll come back with a plan and matched, pre-vetted engineers.
CONTACT