
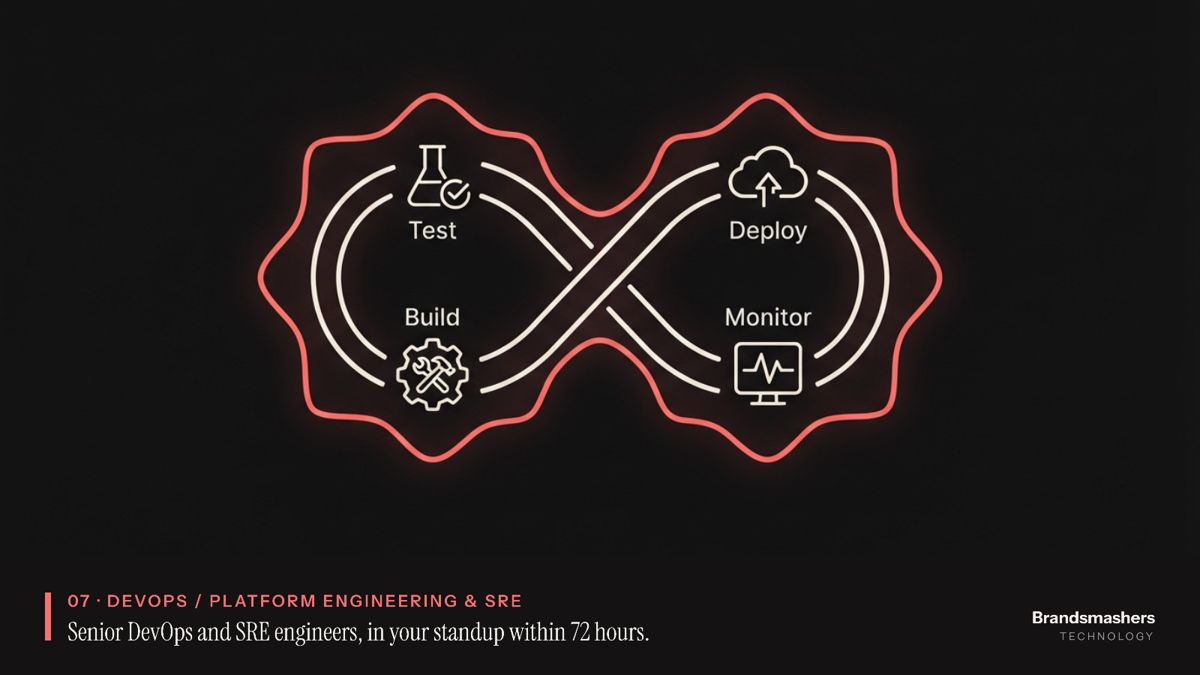
Senior DevOps and SRE engineers, in your standup within 72 hours.
Platform engineers, SREs and Kubernetes specialists who make deployments boring and outages rare.
- 48–72 HOURS
- TOP 3% ENGINEERS
- 100% REPLACEMENT
Most growing teams reach a point where shipping gets harder as the company gets bigger. Pipelines multiply, nobody owns reliability, and the on-call phone belongs to whoever is least able to say no. Hiring a full platform team takes months. Meanwhile releases slow down and incidents repeat. Adding senior engineers who have done this before closes the gap quickly, and they leave behind systems your own people can run.
- 48–72hfrom first call to engineers in your standup
- Top 3%of applicants, vetted for the work
- 100%replacement guarantee on every hire
What we do.
Kubernetes platforms
design, build and run clusters on AWS, Azure and GCP, including networking, ingress, autoscaling, secrets and upgrades.
CI/CD pipelines
with automated tests, security scans and safe rollbacks, so a deploy is a button and not an event.
Infrastructure as code
(Terraform, Pulumi) and environment standardisation, so staging looks like production and anyone can rebuild either.
SRE practice
SLOs, error budgets, on-call rotas and blameless incident reviews.
Observability
metrics, logs, traces and alerts that mean something, and dashboards people actually open.
Cost visibility
tagging and reporting so you can see what each environment and service costs.
Who this is for.
Startups with ten to fifty engineers where every team deploys in its own way.
SaaS companies with recurring outages and no formal on-call or incident process.
Teams moving from virtual machines or manual deploys to Kubernetes.
CTOs who need a platform foundation but cannot wait six months to hire for it.
Companies whose one DevOps person is a single point of failure.
What you get.
Infrastructure defined as code in your repositories, reviewed and versioned.
CI/CD pipelines with tests, scans, approvals where needed and one-step rollback.
A running Kubernetes platform, or improvements to the one you have.
SLOs and error budgets agreed with product and engineering leads.
Monitoring, alerting and dashboards tied to those SLOs.
An on-call rota, escalation paths and incident templates.
Runbooks and a handover session so your team can operate everything.
- Top 3% of applicants
- Start in 48–72 hours
- Dedicated account manager
- 100% replacement guarantee
How we work.
We start by reading what you have: pipelines, cloud accounts, past incidents and the alerts that wake people up. We then agree two or three outcomes, such as faster deploys or fewer outages, and measure the starting point. Work is planned in short cycles, and changes go through your normal review process.
Engineers join your standup, use your tools and report in your channels. Each piece we build is documented as we go. We aim to make ourselves unnecessary: your team should be able to run what we leave behind.
Typical timeline.
An SRE pod working on reliability usually shows early gains inside the first quarter.
- 01
Weeks 1 to 2
onboarding, audit of pipelines, infrastructure and incidents. Priorities agreed.
- 02
Weeks 3 to 6
foundations: infrastructure as code, a standard pipeline, basic monitoring and alerts on the main user journeys.
- 03
Weeks 6 to 10
platform build-out or reliability work, SLOs, on-call rota and incident reviews.
- 04
Weeks 10 to 13
hardening, load testing, documentation and handover. Optional ongoing support.
Proof
A mid-market SaaS company moved from about 4 outages a month to 1, with uptime up from 99.2% to 99.9% over 90 days, using a 4-person SRE pod. A scaling startup cut deploys from a 2-hour manual process to 15 minutes on a Kubernetes platform built from scratch.
Sometimes, for a well-scoped job such as pipelines or a migration. For a platform build or on-call practice, a small pod works better, because the work needs more than one pair of hands and more than one set of holidays.
Related work and reading.
 Case studyStanding up a dedicated SRE pod that hit 99.9% uptime in 90 daysRead the story
 Case studyBuilding a Kubernetes platform from scratch for a scaling startupRead the story
 ArticleWhy every growing startup eventually needs a platform teamRead the article
 ArticleSRE vs. DevOps: what's the actual difference?Read the article
LET'S TALK. Start now.
Tell us what you're building. We'll come back with a plan and matched, pre-vetted engineers.
CONTACT